Tables and data
Learn what tables are and how to use them.
This guide is organized into several groups:
- What is a table? explains the basics if you're new to relational databases.
- Creating and managing tables is the action path: create a table, load rows into it, and link it to other tables.
- How tables are organized is the background: primary keys, relationships, and schemas.
- Reference lists the column data types that Postgres supports.
For saved queries that behave like tables, see Views.
What is a table?#
Tables are where you store your data.
Tables are similar to Excel spreadsheets. They contain columns and rows.
For example, this table has 3 columns named id, name, and description, and 4 rows of data:
id | name | description |
|---|---|---|
| 1 | The Phantom Menace | Two Jedi escape a hostile blockade to find allies and come across a young boy who may bring balance to the Force. |
| 2 | Attack of the Clones | Ten years after the invasion of Naboo, the Galactic Republic is facing a Separatist movement. |
| 3 | Revenge of the Sith | As Obi-Wan pursues a new threat, Anakin acts as a double agent between the Jedi Council and Palpatine and is lured into a sinister plan to rule the galaxy. |
| 4 | Star Wars | Luke Skywalker joins forces with a Jedi Knight, a cocky pilot, a Wookiee and two droids to save the galaxy from the Empire's world-destroying battle station. |
There are a few important differences from a spreadsheet, but it's a good starting point if you're new to relational databases.
Creating and managing tables#
Creating tables#
When creating a table, it's best practice to add columns at the same time.
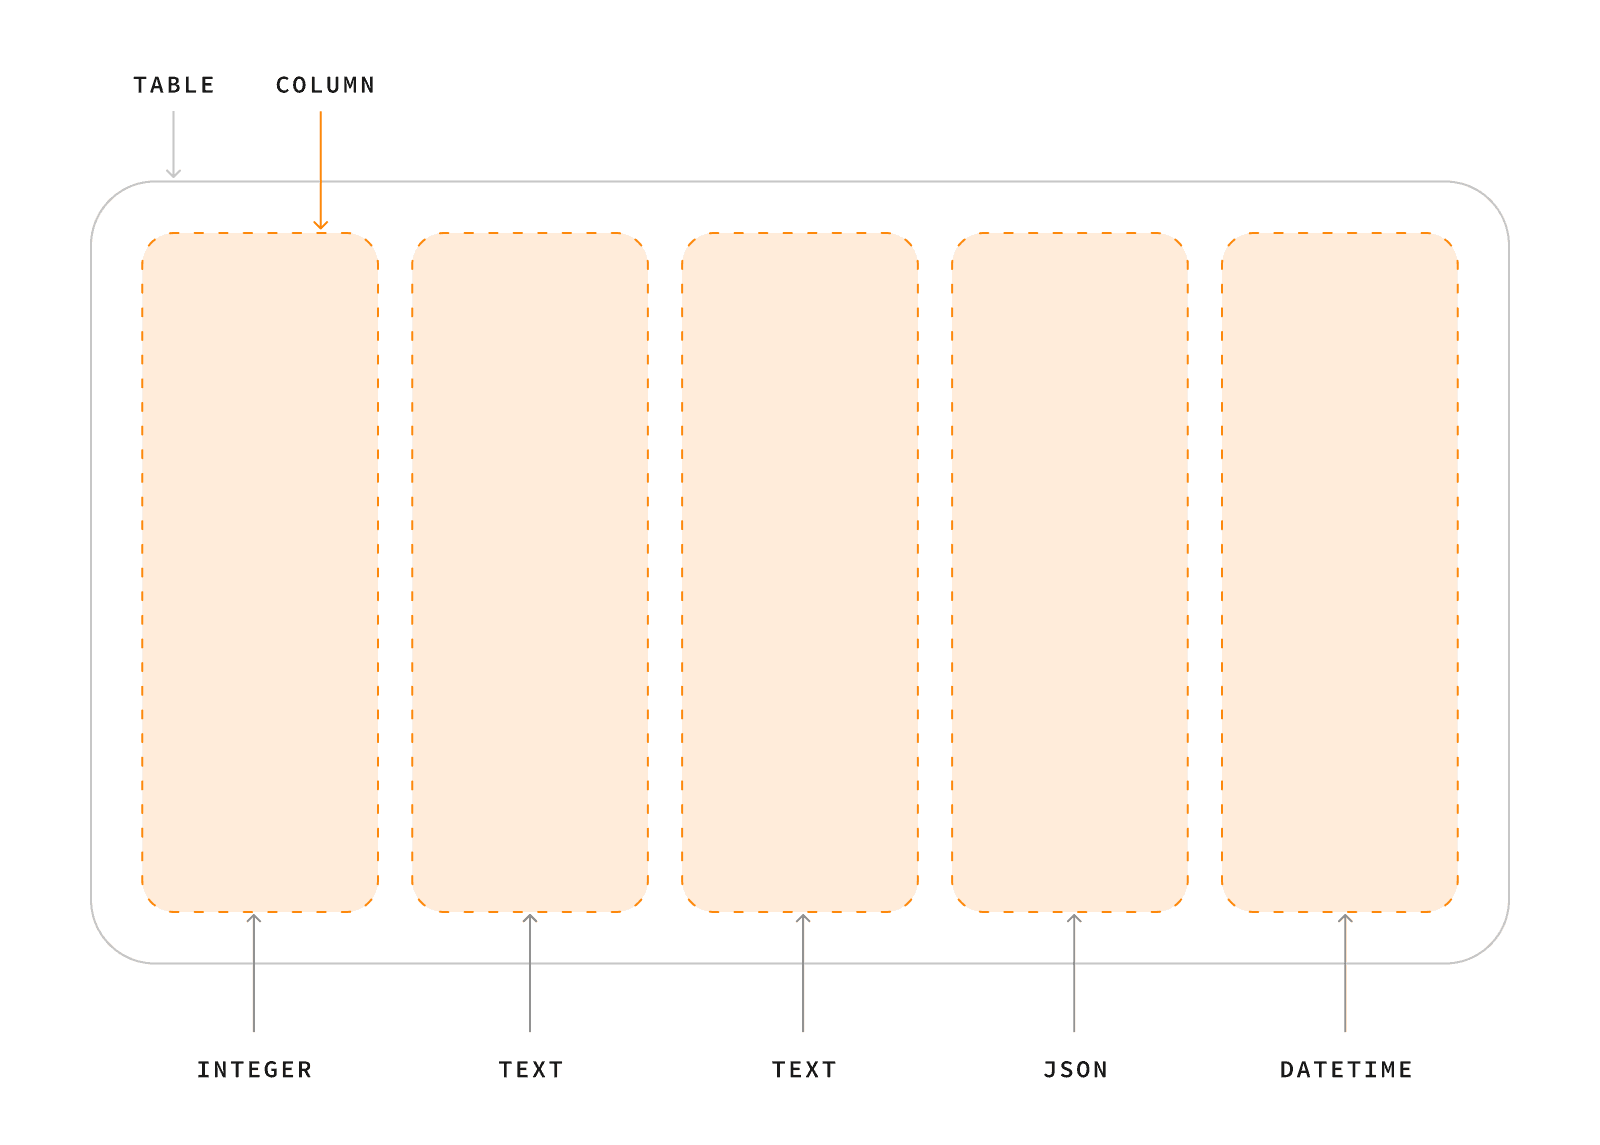
You must define the data type of each column when you create it. You can add and remove columns at any time after creating a table.
Supabase provides several options for creating tables. You can use the Dashboard or create them directly using SQL. We provide a SQL editor within the Dashboard, or you can connect to your database and run the SQL queries yourself.
- Go to the Table Editor page in the Dashboard.
- Click New table.
- Enter
moviesin the Name field. - Under Columns, click Add column and enter
namewith typetext, then adddescriptionwith typetext. Leave theidandcreated_atcolumns as the editor created them. - Click Save.
When naming tables, use lowercase and underscores instead of spaces. For example, use table_name rather than Table Name.
You now have a table with its columns defined. Before you put rows in it, protect it.
Securing your tables#
A table in the public schema is reachable through the Data API. Until you enable row level security and write a policy, anyone holding your project's publishable key can read and write every row in it.
The Table Editor enables row level security for you when you create a table in the Dashboard. When you create a table with SQL, enable it yourself.
Enabling row level security#
-
Enable row level security on the table:
alter table movies enable row level security; -
Add a policy that describes who can read the table. Until one exists, Data API requests return no rows. The table's owner and roles with
BYPASSRLSaren't subject to policies, which is why the same query still returns rows in the SQL editor:create policy "Anyone can read movies"on movies for selectto anon, authenticatedusing ( true );
A policy decides which rows a role reaches, not whether it holds privileges on the table. The Data API roles carry the grants they need by default, so a request that fails with permission denied for table points at a revoked grant rather than a missing policy. See Securing your API.
For insert, update, and delete policies, and for how policies are evaluated, see Row Level Security.
Tables with different readers#
Most applications mix two kinds of table: shared data that everyone reads, and per-person data that only its owner reads. Each kind needs its own policy, and the shared one is the easiest to forget.
movies is the shared kind. The policy above lets anyone browse it, signed in or not.
The watchlists table is the other kind. Each row belongs to the person who created it, and only that person can read it:
create table watchlists ( id bigint generated always as identity primary key, user_id uuid not null references auth.users default auth.uid(), movie_id bigint not null references movies);alter table watchlists enable row level security;create policy "Users can read their own watchlist"on watchlists for selectto authenticatedusing ( (select auth.uid()) = user_id );create policy "Users can add to their own watchlist"on watchlists for insertto authenticatedwith check ( (select auth.uid()) = user_id );Give both tables a policy, even when one of them is using ( true ). A shared table with row level security enabled and no policy is as unreachable as a private one.
Verifying your tables#
Confirm that every table exists and is protected before you build against it.
-
List the tables in the
publicschema and whether row level security is enabled on each one:select tablename, rowsecurityfrom pg_tableswhere schemaname = 'public'order by tablename; -
Check that every table you meant to create appears in the results, and that
rowsecurityistruefor each one. -
List the policies on those tables:
select tablename, policyname, cmd, rolesfrom pg_policieswhere schemaname = 'public'order by tablename, policyname; -
Check that every table has at least one policy, and that any table meant to be readable by signed-out visitors lists
anonamong its roles.
Loading data#
There are several ways to load data in Supabase. You can load data directly into the database, or use the Data API. If you're loading large data sets, follow the bulk data loading instructions.
The read-only policy from Securing your tables rejects inserts through the Data API. Run the client examples below against a table that has an insert policy for the role you're using, or load the data over a direct connection instead.
Basic data loading#
insert into movies (name, description)values ( 'The Empire Strikes Back', 'After the Rebels are brutally overpowered by the Empire on the ice planet Hoth, Luke Skywalker begins Jedi training with Yoda.' ), ( 'Return of the Jedi', 'After a daring mission to rescue Han Solo from Jabba the Hutt, the Rebels dispatch to Endor to destroy the second Death Star.' );Bulk data loading#
When inserting large data sets, use Postgres's COPY command.
This loads data directly from a file into a table. COPY accepts text, CSV, and binary input.
For example, to load a CSV file into your movies table:
"The Empire Strikes Back","After the Rebels are brutally overpowered by the Empire on the ice planet Hoth, Luke Skywalker begins Jedi training with Yoda.""Return of the Jedi","After a daring mission to rescue Han Solo from Jabba the Hutt, the Rebels dispatch to Endor to destroy the second Death Star."Set DATABASE_URL to your direct connection string, then load the file with the COPY command. Name the columns the file contains, so Postgres doesn't expect a value for id:
psql "$DATABASE_URL" \ -c "\COPY movies (name, description) FROM './movies.csv' WITH (FORMAT csv);"You can also pass options such as DELIMITER and HEADER, as defined in the Postgres COPY docs. HEADER skips the first line of the file, so use it only when that line names the columns:
psql "$DATABASE_URL" \ -c "\COPY movies (name, description) FROM './movies-with-header.csv' WITH (FORMAT csv, HEADER, DELIMITER ';');"If you receive an error FATAL: password authentication failed for user "postgres", reset your database password in Database Settings and try again.
Joining tables with foreign keys#
Foreign keys are how you express a relationship between two tables. For what that relationship means, see Relationships between tables.
In the movies example above, you might want to add a category for each movie, such as Action or Documentary.
Create a new table called categories and link it to the movies table.
create table categories ( id bigint generated always as identity primary key, name text -- category name);alter table movies add column category_id bigint references categories;You can also create many-to-many relationships by creating a join table. For example, consider this situation:
- You have a list of
movies. - A movie can have several
actors. - An
actorcan perform in several movies.
create table actors ( id bigint generated by default as identity primary key, name text);create table performances ( id bigint generated by default as identity primary key, movie_id bigint not null references movies, actor_id bigint not null references actors);How tables are organized#
Background on the pieces the procedures above use. Read these when you want to know why a table is shaped the way it is.
Primary keys#
A table can have a primary key, a unique identifier for every row of data. A few tips for primary keys:
- Create a primary key for every table in your database.
- You can use any column as a primary key, as long as it is unique for every row.
- It's common to use a
uuidtype or a numberedidentitycolumn as your primary key.
create table movies ( id bigint generated always as identity primary key);In the example above, you:
- Created a column called
id. - Assigned the data type
bigint. - Instructed the database that this column is
generated always as identity, so Postgres automatically assigns it a unique number. - Used it as the
primary key, because the value is unique.
You can also use generated by default as identity, which lets you insert your own unique values.
create table movies ( id bigint generated by default as identity primary key);Relationships between tables#
Tables can be joined together using foreign keys.
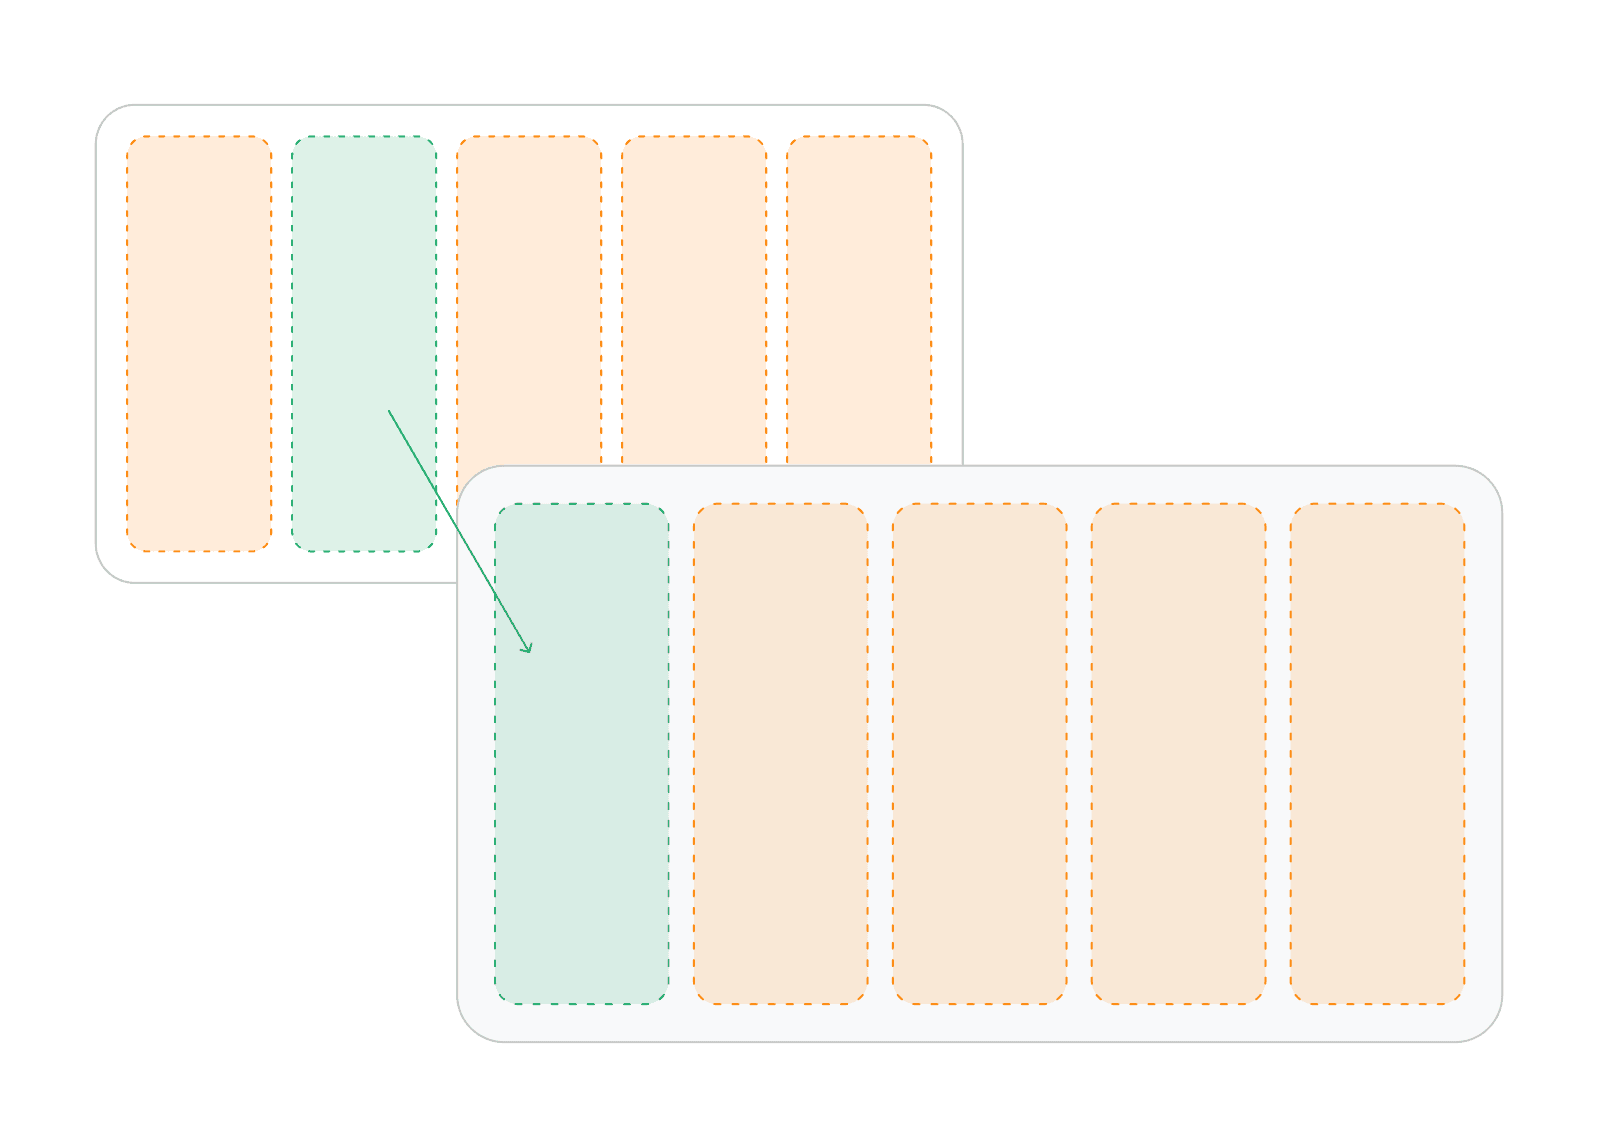
This is where the term relational comes from, because data typically forms some sort of relationship.
To create a foreign key, see Joining tables with foreign keys.
Schemas#
Tables belong to schemas. Schemas are a way of organizing your tables, often for security reasons.
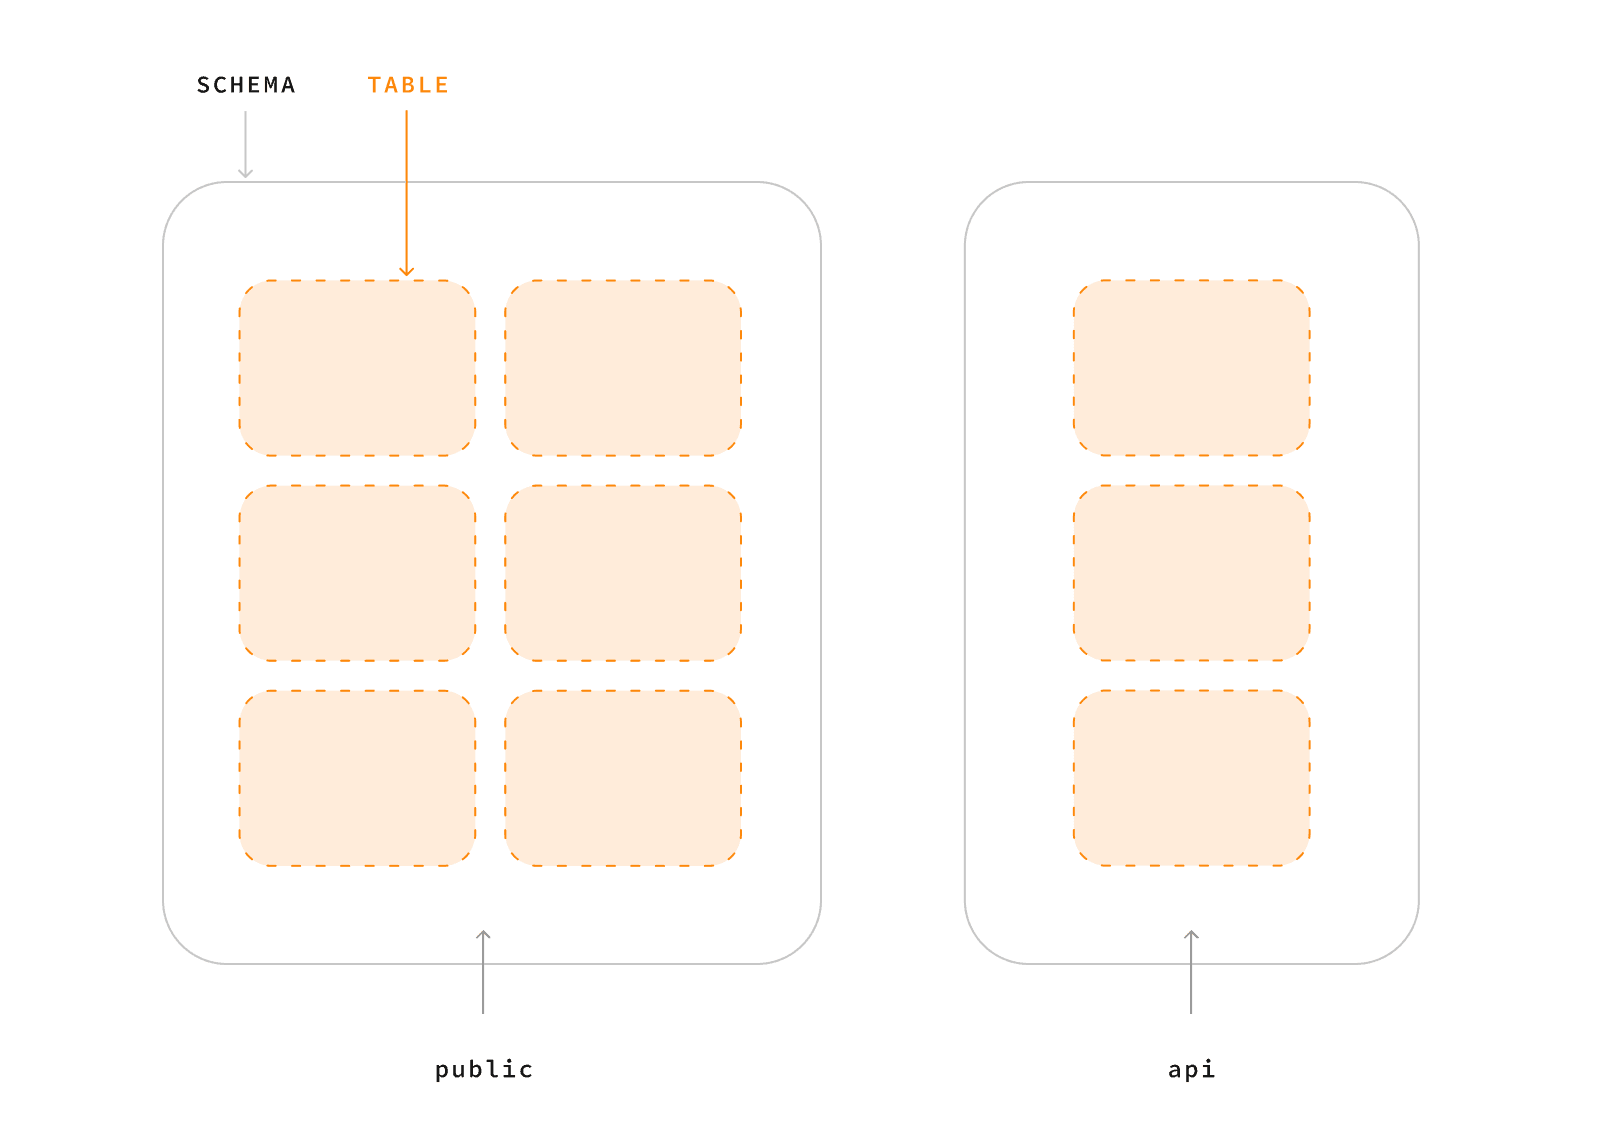
If you don't explicitly pass a schema when creating a table, Postgres creates the table in the first schema in the current search_path. The default path is "$user", public, so on a new project that's the public schema.
You can create schemas to organize tables. For example, you might want a private schema that's hidden from your API:
create schema private;Now you can create tables inside the private schema:
create table private.salaries ( id bigint generated by default as identity primary key, salary numeric not null, actor_id bigint not null references public.actors);A custom schema isn't reachable through the Supabase Data API until you expose it and grant the appropriate permissions. See Using custom schemas for the steps, and Securing your API for security best practices around schema exposure.
Reference#
Reference material for choosing a column type.
Choosing a type#
Postgres offers several near-equivalent types for the same job. These defaults are safe:
- Timestamps: prefer
timestamptzovertimestamp.timestamptzrecords the instant and renders it in the session's time zone.timestampstores only the date and time fields, so the same stored value means different moments to clients in different zones. Reach fortimestampwhen you mean a wall-clock time rather than an instant, such as a 9 a.m. opening time that holds in every location. - Text: prefer
textovervarchar(n). The two use the same storage representation, andtexthas no declared limit to migrate later. Add a check constraint when you need to bound the length. - Money and other exact decimals: prefer
numeric.realanddouble precisioncan't represent values such as0.10exactly, so totals drift as they accumulate.moneyis exact, but its fractional precision and formatting follow the server'slc_monetarysetting, so the same value reads differently on another server. - Identifiers: prefer
bigintoverinteger. Anintegertops out at 2,147,483,647, and an identity column doesn't reuse the values it skips, so a table reaches that ceiling before it holds that many rows.
Data types#
Every column has a data type. Postgres provides many default types, and you can design your own or use extensions if the default types don't fit your needs. You can use any data type that Postgres supports via the SQL editor. The Table Editor supports a subset of these, which keeps the experience focused for people with less database experience.
Show/Hide default data types
Name | Aliases | Description |
|---|---|---|
bigint | int8 | signed eight-byte integer |
bigserial | serial8 | autoincrementing eight-byte integer |
bit | fixed-length bit string | |
bit varying | varbit | variable-length bit string |
boolean | bool | logical Boolean (true/false) |
box | rectangular box on a plane | |
bytea | binary data (“byte array”) | |
character | char | fixed-length character string |
character varying | varchar | variable-length character string |
cidr | IPv4 or IPv6 network address | |
circle | circle on a plane | |
date | calendar date (year, month, day) | |
double precision | float8 | double precision floating-point number (8 bytes) |
inet | IPv4 or IPv6 host address | |
integer | int, int4 | signed four-byte integer |
interval [ fields ] | time span | |
json | textual JSON data | |
jsonb | binary JSON data, decomposed | |
line | infinite line on a plane | |
lseg | line segment on a plane | |
macaddr | MAC (Media Access Control) address | |
macaddr8 | MAC (Media Access Control) address (EUI-64 format) | |
money | currency amount | |
numeric | decimal | exact numeric of selectable precision |
path | geometric path on a plane | |
pg_lsn | Postgres Log Sequence Number | |
pg_snapshot | user-level transaction ID snapshot | |
point | geometric point on a plane | |
polygon | closed geometric path on a plane | |
real | float4 | single precision floating-point number (4 bytes) |
smallint | int2 | signed two-byte integer |
smallserial | serial2 | autoincrementing two-byte integer |
serial | serial4 | autoincrementing four-byte integer |
text | variable-length character string | |
time [ without time zone ] | time of day (no time zone) | |
time with time zone | timetz | time of day, including time zone |
timestamp [ without time zone ] | date and time (no time zone) | |
timestamp with time zone | timestamptz | date and time, including time zone |
tsquery | text search query | |
tsvector | text search document | |
txid_snapshot | user-level transaction ID snapshot (deprecated; see pg_snapshot) | |
uuid | universally unique identifier | |
xml | XML data |
You can cast columns from one type to another, but some types are incompatible.
For example, if you cast a timestamp to a date, you lose all the time information that was previously saved.